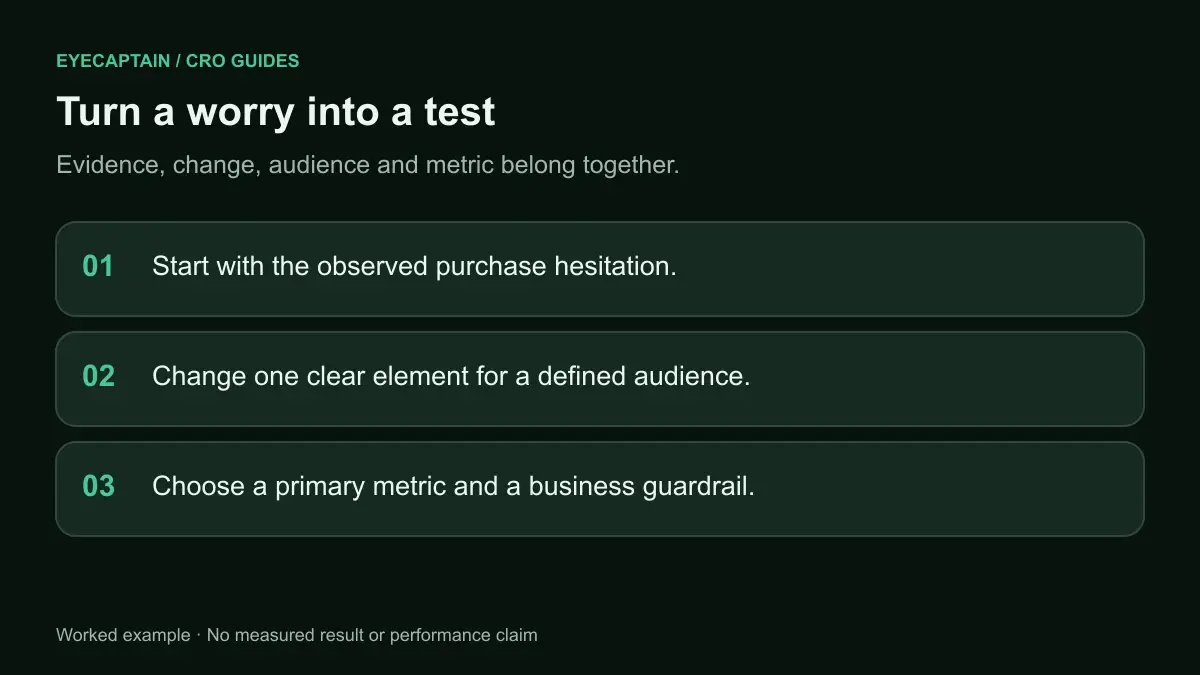

A good A/B test hypothesis follows one template: "Because we observed X, we believe changing Y for audience Z will improve metric M." It names the evidence, the exact change, who sees it, and how success is measured. If any of the four parts is missing, the test can run but you will not learn much from the result.
What is an A/B test hypothesis?
An A/B test hypothesis is a written prediction that links a specific change to a specific outcome, along with the reason you expect it. It is written before the test is designed, and it decides what you build, who sees it, and what you measure.
A hypothesis is not the same as an idea. "Try a green button" is an idea. A hypothesis explains why the button should change, for whom, and what number should move. That extra structure is what turns a test into learning, because when the result comes in you can say which belief it supported or broke.
This article is about writing the hypothesis itself. For the statistics of reading results, see our posts on the peeking problem and on Bayesian vs frequentist testing.
What is the best A/B test hypothesis template?
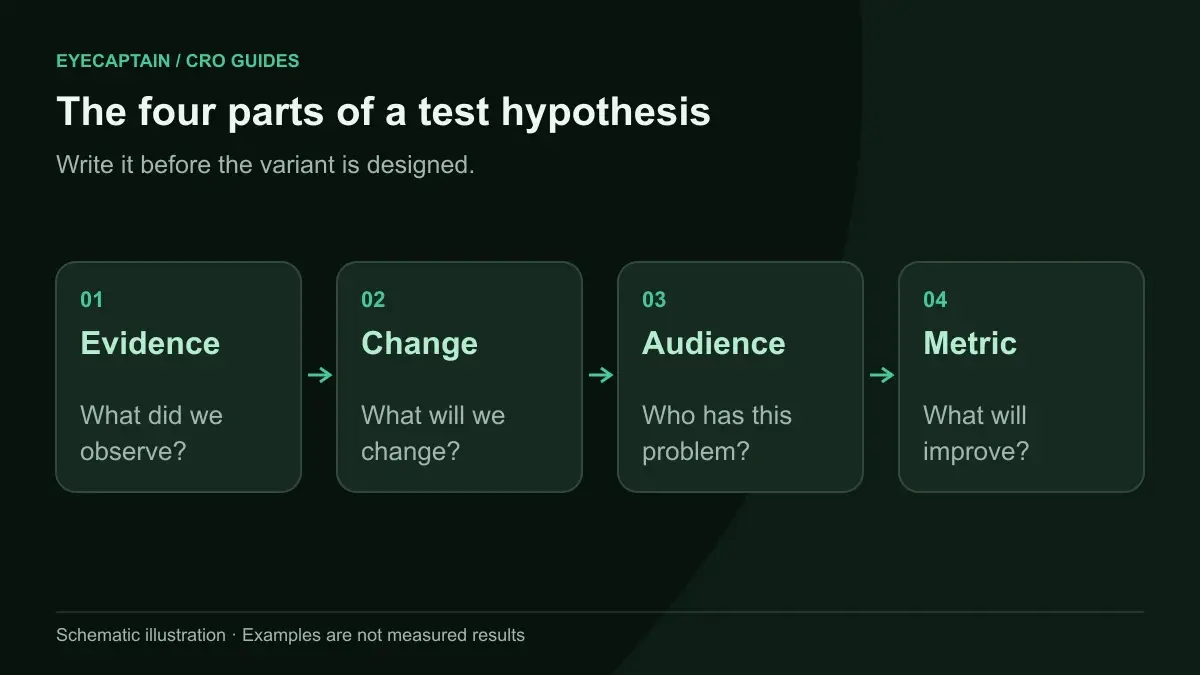
The most useful template has four slots:
Because we observed [X: evidence], we believe that changing [Y: the specific element and change] for [Z: the audience or page] will improve [M: the primary metric].
Each slot does a job:
- X, the observation, forces you to name evidence. Analytics, heatmaps, session recordings, user tests, support tickets, reviews, and audit findings all count. "The CEO thinks so" does not.
- Y, the change, must be specific enough that a designer and developer could build it without asking questions.
- Z, the audience, sets the scope: all visitors, mobile only, new visitors, paid traffic, a single product category.
- M, the metric, is the one number that decides the test. Pick it before launch.
Many teams add a fifth line, "We will know this is true when M changes, and we will watch guardrail metrics G." Guardrails are numbers that must not get worse, such as refund rate, average order value, or lead quality.
How do you write an A/B test hypothesis step by step?
Start from evidence, not from the solution. The steps below use a hypothetical project management SaaS and its pricing page as the example.
- Write the observation first. Describe what you saw in one or two sentences, with the source. Example: "Session recordings show mobile visitors scrolling up and down between the plan cards and the feature table."
- Name the problem behind it. "Visitors cannot compare plans without leaving the cards."
- Propose one change that addresses that problem. "Add the three most important features as a short list inside each plan card."
- Define the audience. "Mobile visitors to the pricing page."
- Pick the primary metric closest to the change that still matters to the business. "Clicks on any plan's Start trial button" or, better if volume allows, "trial starts."
- List guardrails. "Paid conversion from trial must not drop."
- Write down what you will do with each outcome. If it wins, ship it and test the same pattern on desktop. If it loses, review recordings of the variant before the next idea.
Step 7 is often skipped. If no result would change what you do next, the test is not worth the traffic.
What do good and bad A/B test hypotheses look like?
Bad hypotheses are vague about the change, missing evidence, or measured on a metric that cannot tell you anything. Here are five pairs, each fixed using the template.
1. The button color hypothesis
Bad: "A red button will convert better."
Good: "Because a predictive heatmap and a scroll map show the beige Add to cart button gets little attention on mobile product pages, we believe changing it to a high contrast color and full width for mobile visitors will increase add to cart rate."
The fix: the color itself was never the point. The evidence is about visibility, so the change targets visibility and the metric is the one closest to the button.
2. The headline hypothesis
Bad: "A better headline will increase conversions."
Good: "Because support chats show new visitors often ask whether the tool works with Shopify, we believe changing the homepage headline from 'Smarter inventory' to 'Inventory forecasting for Shopify stores' for new visitors will increase trial signups."
The fix: "better" is not a change. The good version states both headlines, the reason, and the audience.
3. The social proof hypothesis
Bad: "Adding testimonials builds trust."
Good: "Because exit survey answers mention doubts about whether the course suits beginners, we believe adding two testimonials from beginner students directly under the Enroll button on the course page for all visitors will increase enrollments."
The fix: the bad version is a general belief, not a testable prediction. The good one ties a specific kind of proof to a specific objection and places it where the decision happens.
4. The form length hypothesis
Bad: "Shorter forms convert better, so remove fields."
Good: "Because form analytics show the highest abandonment at the 'Company size' and 'Budget' fields, we believe removing those two fields from the quote request form for paid search visitors will increase completed quote requests, while sales qualified lead rate stays the same."
The fix: it names the fields and adds a guardrail. Removing qualification fields can raise volume and lower quality, so lead quality must be watched.
5. The redesign hypothesis
Bad: "The new product page design will improve the user experience."
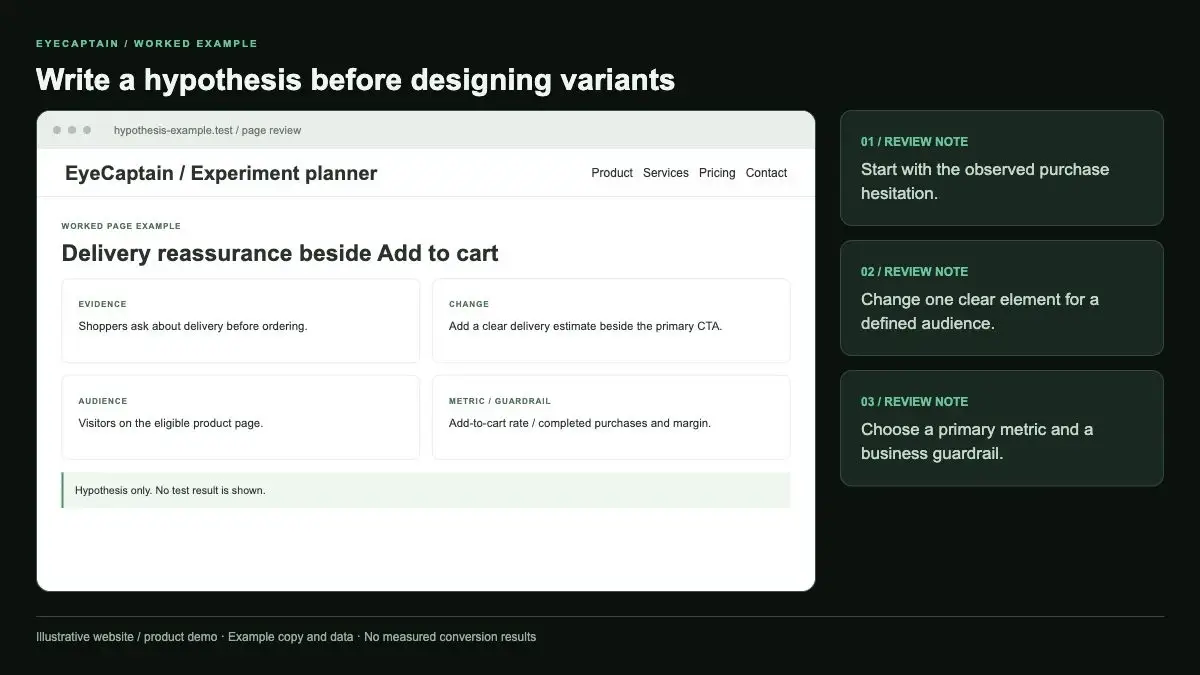
Good: "Because recordings show mobile visitors scroll past the long description and rarely reach reviews or shipping details, we believe moving the review summary and delivery estimate above the description on mobile product pages will increase add to cart rate."
The fix: "user experience" is not a metric, and a full redesign changes too many things at once. If it wins, you will not know why. Test the change the evidence supports.
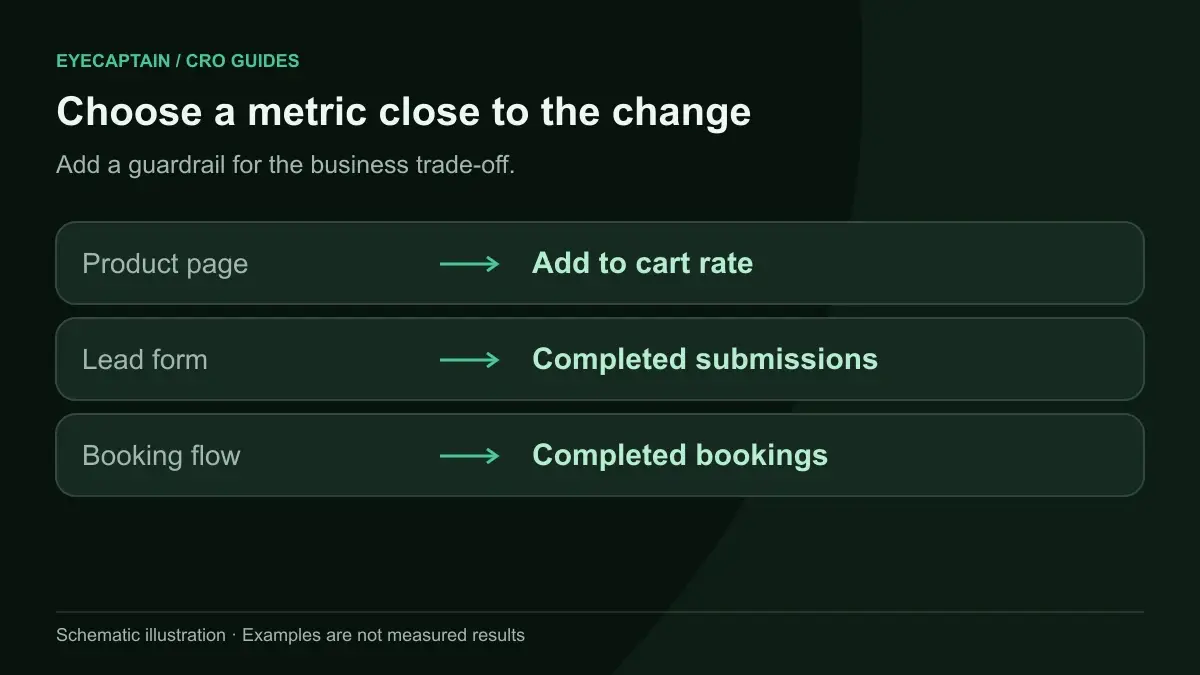
How do you choose the right metric for a hypothesis?
Choose the metric closest to the change that still reflects business value, and decide it before launch. A change to a product page button should be measured on add to cart rate, with orders as a secondary metric. A change to a checkout step should be measured on completed orders.